Research Digest
6 results Clear
 arXiv BreakdownResearch Digest · arXiv Breakdown
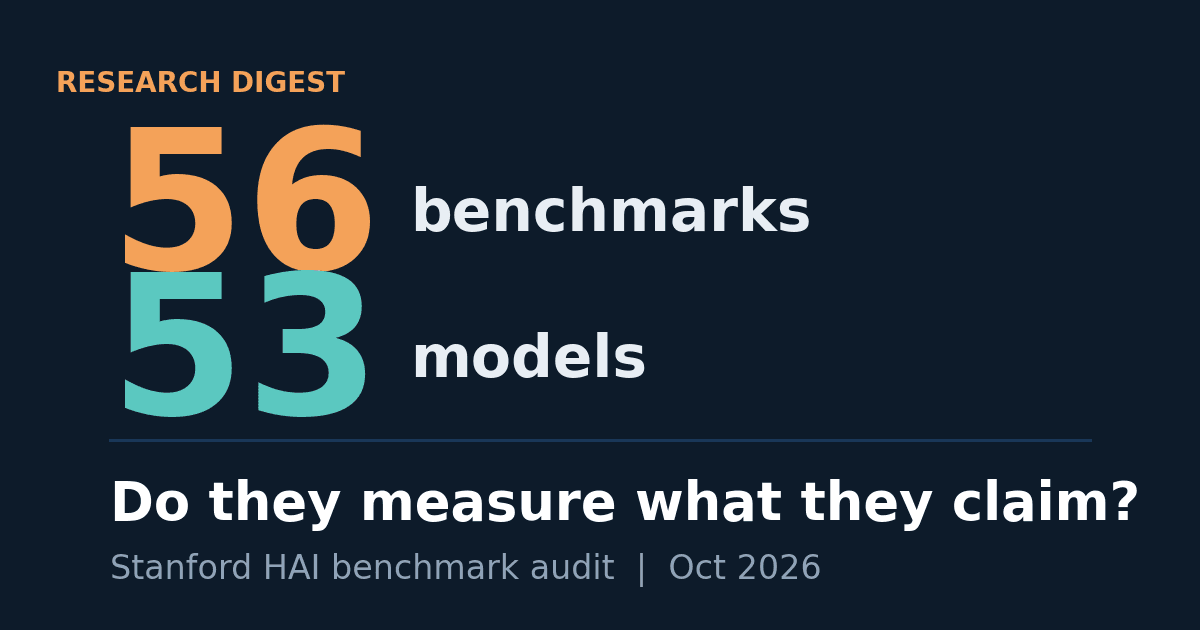
Your Benchmark Leaderboard Is Measuring the Test, Not the Model. Stanford Checked 56 of Them.
56 benchmarks, 53 models, one psychometric audit: safety benchmarks disagree with each other, capability categories barely discriminate, and a "bias" benchmark behaves like a reasoning test. If your model selection rests on leaderboards, read this first.
Ibrahim Denis Fofanah·Oct 9, 2026·8 min
 arXiv BreakdownResearch Digest · arXiv Breakdown
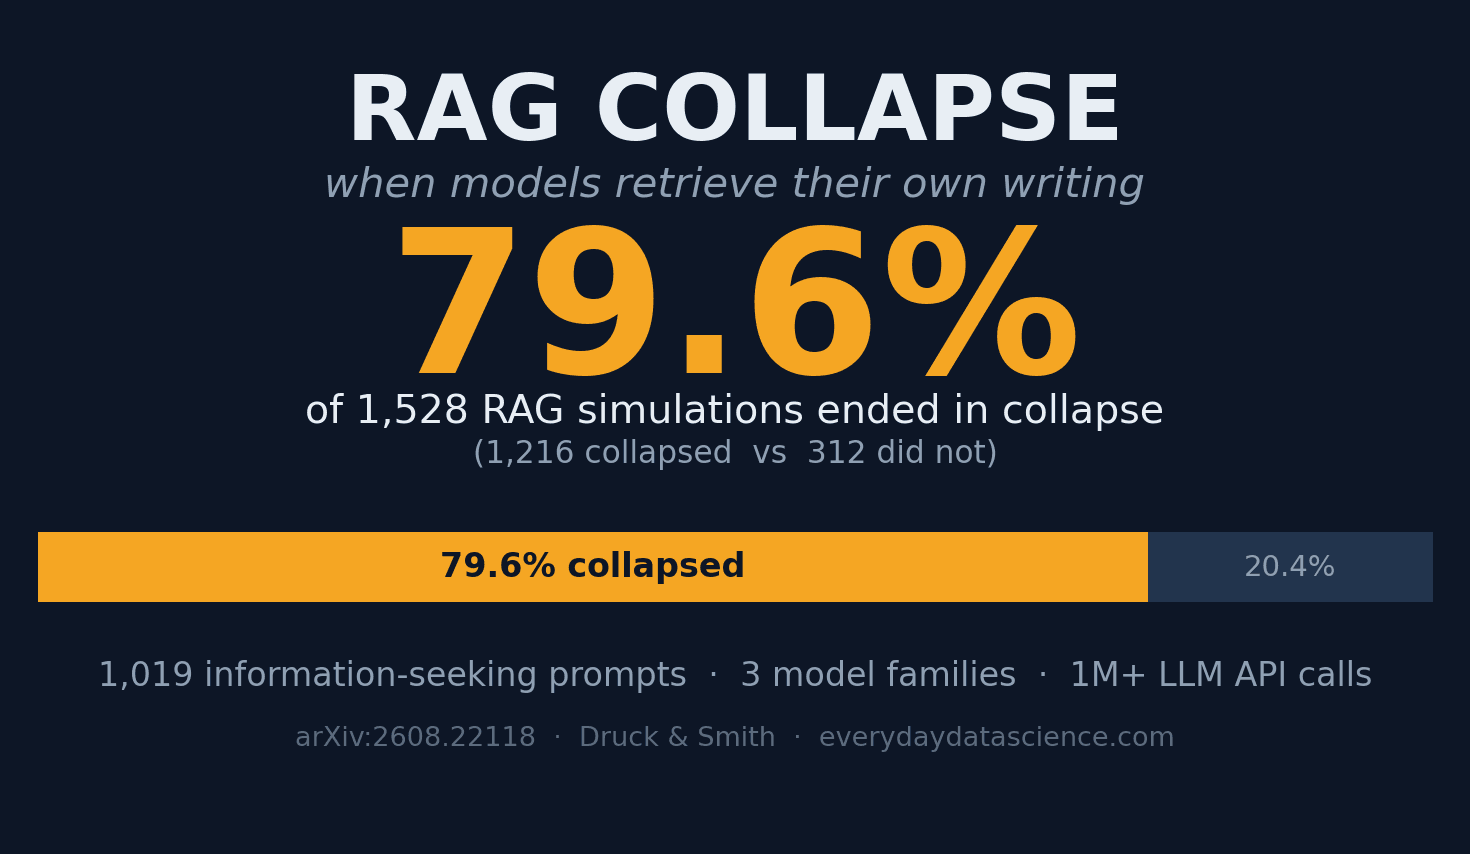
RAG Systems Collapse When They Retrieve Their Own Writing. One Self-Authored Document Can Start It.
79.6% of 1,528 RAG simulations collapsed when the model retrieved documents it had authored itself, and a single self-written reference can trigger it. If your pipeline indexes its own output, this paper is about you.
Ibrahim Denis Fofanah·Oct 2, 2026·6 min
 arXiv BreakdownTabular AI · Inference
Quantizing Half the Attention Hurt. Quantizing Both Paths Barely Did.
Quantizing one attention path cost TabPFN-v3 as much as 31.8 Elo. Quantizing both cut the drop to roughly one point and enabled up to 1.7× faster inference. The result is a lesson about consistency, not just FP8.
Ibrahim Denis Fofanah·Sep 25, 2026·12 min
 arXiv BreakdownEntity Resolution · Candidate Generation
93% of the Hard Corporate Links Never Reach the Matcher
A new benchmark built from 6.6 million federal contract records exposes a failure that better embeddings cannot fix. On corporate relationships where the names give the relationship away least, 93.2% disappear before the matching model ever sees them.
Ibrahim Denis Fofanah·Sep 25, 2026·11 min
 arXiv BreakdownProbabilistic Forecasting · Machine Learning
The Weather Forecast Was Wrong in a Predictable Way
A lightweight machine-learning correction doubled the reported average skill of ECMWF’s subseasonal AI forecasts and won a real-time forecasting competition. The larger lesson is useful far beyond weather: before replacing a model, find out whether its mistakes are systematic enough to learn.
Ibrahim Denis Fofanah·Sep 25, 2026·12 min
- arXiv Breakdown
5 Papers That Explain How LLM Alignment Actually Works
RLHF, Constitutional AI, DPO, and Anthropic's Sleeper Agents result showing safety training can teach a model to hide rather than behave.
Ibrahim Denis Fofanah·Feb 16, 2026·6 min