Agentic AI
3 results Clear
 Benchmark WatchBuilding Agentic AI Systems · Benchmark Watch
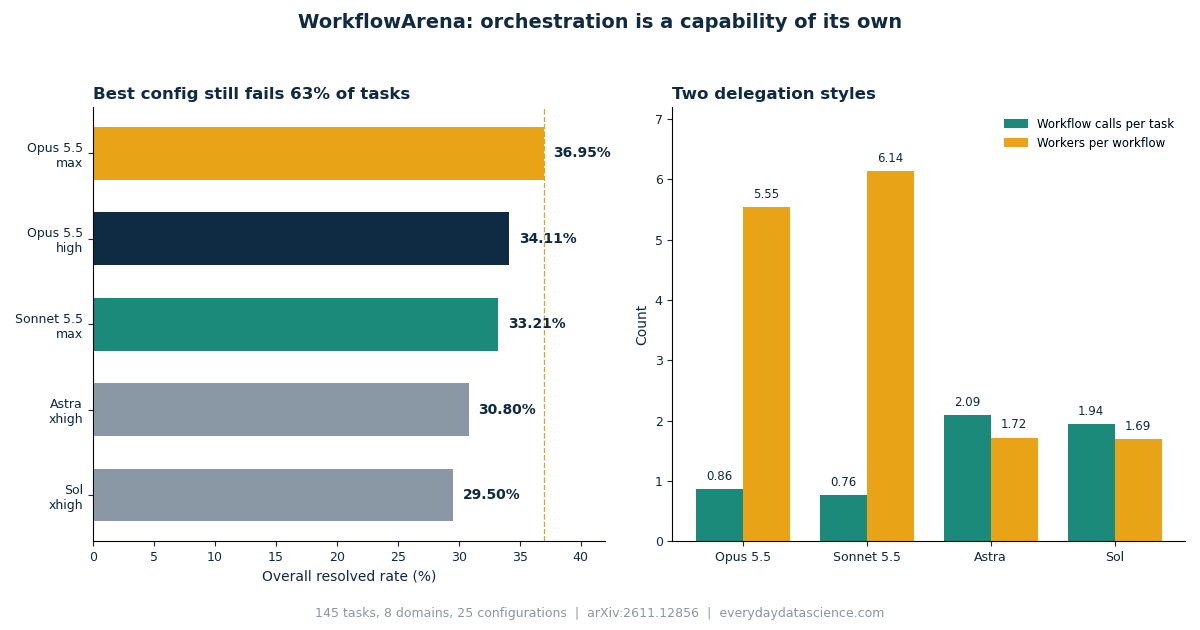
Multi-Agent Systems Can Now Write Their Own Workflows. The Best One Still Fails 63% of Long Tasks
WorkflowArena tests 145 long-horizon tasks across 8 domains and lets each model organize its own workers. The best configuration resolves 36.95%, and orchestration quality alone lifts weaker executors by 6.4 points.
Ibrahim Denis Fofanah·Nov 17, 2026·15 min
 Benchmark WatchAgent Evaluation · Benchmark Watch
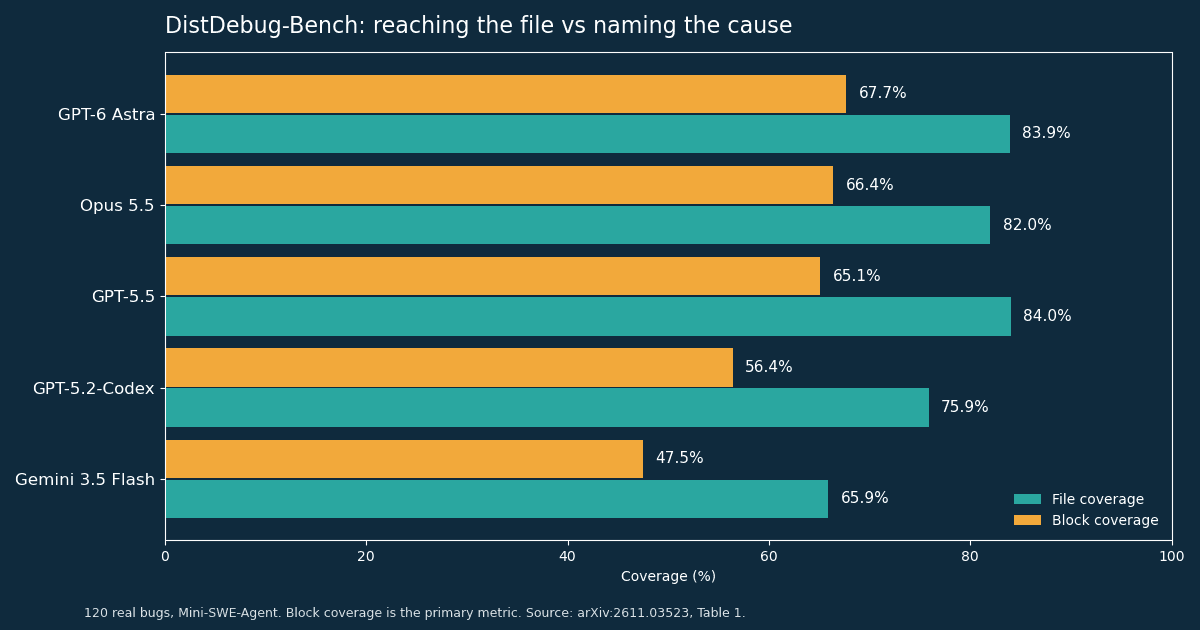
Agents Find the File and Miss the Cause, and the Gap Grows on Thin Evidence
On 120 real distributed-system bugs, the best agent finds the right file 83.9% of the time but names the causal code block only 67.7% of the time. The gap widens to a 29.8 point drop on reports that name no method and carry no stack trace.
Ibrahim Denis Fofanah·Nov 4, 2026·12 min
 Benchmark WatchBuilding Agentic AI Systems · Benchmark Watch
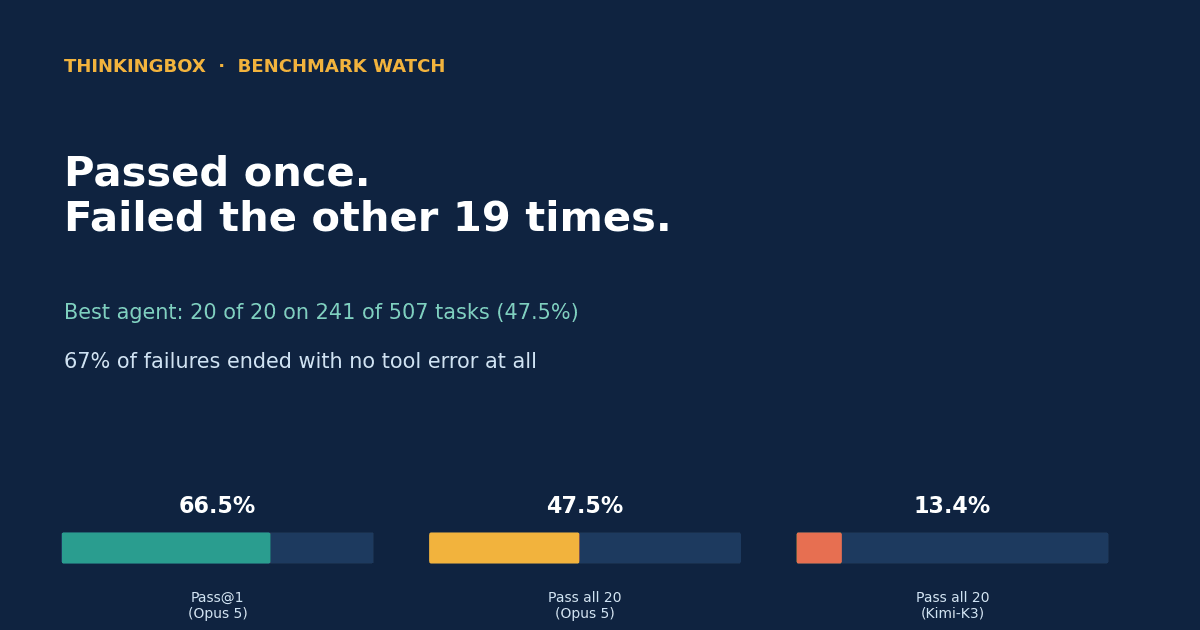
Passed Once Is Not Reliable: ThinkingBox Grades Agents on the Database, Not the Demo
ThinkingBox checks the final database state after an agent finishes, not its summary. Across 121,680 trials, 79,853 failed, and 67% of failures ended with no tool error. One good demo is not reliability.
Ibrahim Denis Fofanah·Oct 15, 2026·7 min